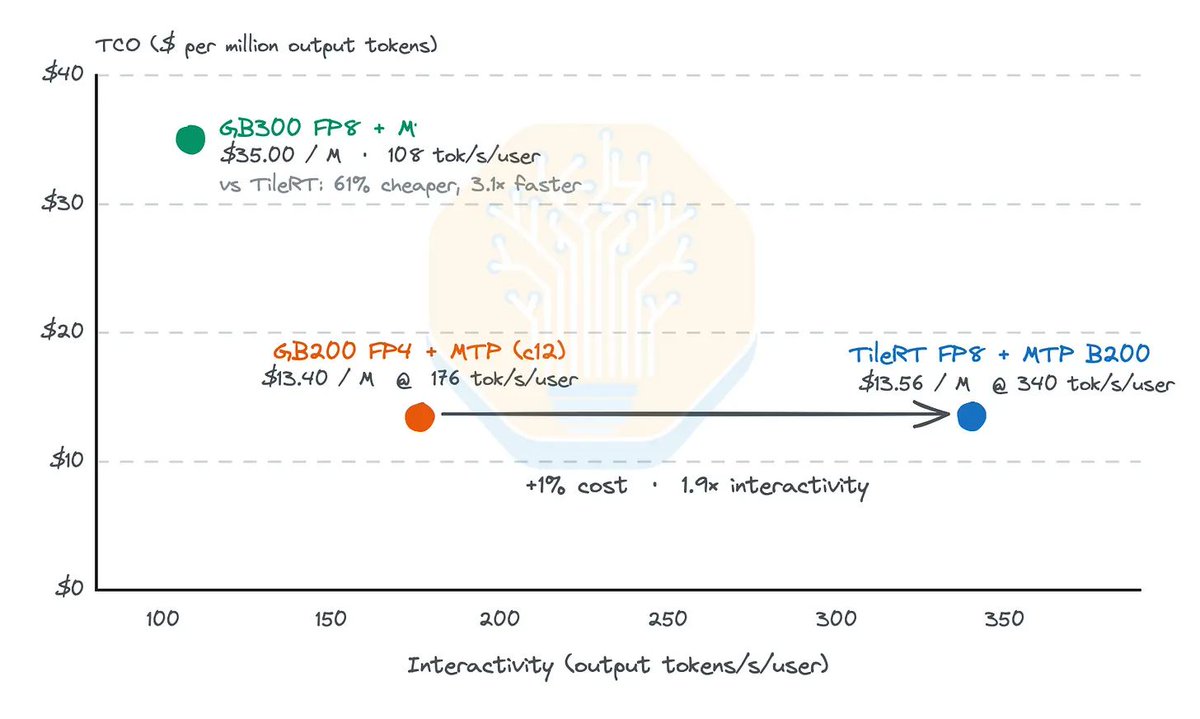
SemiAnalysis — TileRT compiles the whole model into one persistent GPU kernel, claiming 1.9x decode interactivity on the same Blackwell chips

X post

SemiAnalysis — TileRT compiles the whole model into one persistent GPU kernel, claiming 1.9x decode interactivity on the same Blackwell chips

Software squeezing 2x more interactive inference out of the same NVIDIA silicon cuts at the core pitch of the dedicated inference-ASIC vendors (Groq, Cerebras, SambaNova) — and raises effective utilization per deployed GPU, which feeds the power-per-rack math the AI-power lane tracks.

SemiAnalysis✓ @SemiAnalysis_
Aug 11

ALERT🚨 TILERT from@TileRT_AII TO BOOST DECODE INTERACTIVITY BY 1.9X AT THE SAME PER-TOKEN COST ON THE SAME NVIDIA BLACKWELL GPUs. What does this mean for Groq/Cerebras/SambaNova? 👇️ 1/5pic.x.com/lTBJA1rgO0gO0
Why it's worth your time

Software squeezing 2x more interactive inference out of the same NVIDIA silicon cuts at the core pitch of the dedicated inference-ASIC vendors (Groq, Cerebras, SambaNova) — and raises effective utilization per deployed GPU, which feeds the power-per-rack math the AI-power lane tracks.

7 events